Events
Lab seminars and workshops give researchers a place to discuss results while projects are underway.
Upcoming events
No upcoming events have been announced.
Seminars
All times are local to Montréal.
Upcoming seminars
-
Emergence of mutants in bacterial populations: Revisiting Luria & Delbrück with stochastic simulations
Research overview and speaker bio
Research overview
The Luria–Delbrück fluctuation test estimates how often bacteria mutate by counting mutants in independently grown cultures. Frénoy’s research uses stochastic simulations to examine how differences in growth, cell death and sampling affect the mutation rates inferred from those counts.
Speaker bio
Antoine Frénoy is an assistant professor at Université Grenoble Alpes and a member of the Aptikal team at the Laboratoire d’informatique de Grenoble. He uses mathematical and computational models to study microbial evolution.
-
GPM: The Gaussian Pancake Mechanism for Planting Undetectable Backdoors in Differential Privacy
Research overview and speaker bio
Research overview
Differentially private systems often add Gaussian noise before releasing a statistic. Sun and his co-authors construct a malicious noise sampler that is computationally difficult to distinguish from an honest one, yet lets an attacker recover information that the release was meant to protect.
Speaker bio
Haochen Sun is a doctoral candidate in the Data Systems Group at the University of Waterloo, supervised by Xi He. His research examines how to test the privacy guarantees of data systems.
-
Statistical genomics and intelligence learning
Research overview and speaker bio
Research overview
Zhang’s group develops statistical and machine learning methods to study gene expression in individual cells and across tissues. One focus is how to account for measurement error when drawing biological conclusions from single-cell and spatial data.
Speaker bio
Qihuang Zhang is an assistant professor in McGill University’s Department of Epidemiology, Biostatistics and Occupational Health. He leads the Statistical Genomics and Intelligence Learning Laboratory.


Past seminars
-
From Q-learning to Near-Equivalent Policies: Expanding Treatment Options in Precision Medicine
Abstract and speaker bio
Abstract
Precision medicine aims to tailor therapeutic decisions to individual patient characteristics and evolving clinical information. Dynamic treatment regimes (DTRs) provide a framework for developing sequential treatment strategies, with the objective of optimizing patient outcomes. Among the statistical methods used to estimate DTRs, Q-learning is a regression-based approach that relies on backward recursion to identify optimal treatment decisions at successive stages.
In this presentation, we first introduce the fundamental principles of Q-learning, highlighting how sequential decision rules are estimated from retrospective data. We then discuss a limitation of the conventional framework: its focus on identifying a single optimal treatment policy, even when several treatment options may yield very similar expected outcomes. To address this limitation, we introduce Near-Equivalent Q-learning (NEQ), an extension that constructs families of treatment policies whose expected values remain within a specified tolerance of the optimum. The proposed approach relies on two user-specified hyperparameters: a tolerance parameter, ε, controlling the allowable departure from the optimal expected value, and a selection stage, tε, determining when the tolerance criterion is applied during backward recursion.
We illustrate the proposed framework through three settings: a single-stage treatment decision problem highlighting regions of treatment indifference, a multi-stage simulated oncology model examining the influence of the two hyperparameters, and an application to the Systolic Blood Pressure Intervention Trial investigating near-equivalent antihypertensive treatment recommendations. Together, these examples demonstrate how extending Q-learning beyond a single optimal policy can provide greater flexibility in sequential treatment decision-making.
Speaker bio
Sophia Yazzourh is a postdoctoral researcher at McGill University. She develops statistical methods for choosing sequences of treatments in precision medicine.
-
Computational identification of spatial niches in cancer
Abstract and speaker bio
Abstract
Pancreatic ductal adenocarcinoma (PDAC) is an aggressive cancer with poor prognosis and marked cellular heterogeneity. This heterogeneity makes tumor classification difficult, despite the importance of identifying clinically and biologically meaningful tumor states for therapeutic interpretation. Transcriptomic data provide a natural framework to study this problem at different scales. Single-cell RNA sequencing gives access to the transcriptional state of individual cells, while spatial transcriptomics retains information about their organization within the tissue. Together, these technologies make it possible to investigate the broader cellular environments in which these states occur. Our work focuses on the inference of tumor ecosystems from such transcriptomic data: identifying reproducible cellular and transcriptional configurations that can be defined, compared, and ultimately classified. This inference problem sits in a methodological landscape that includes heterogeneous datasets, approaches, and a wide range of analysis strategies, none of which is specifically designed to benchmark ecosystem inference as a task in itself. We propose to formulate this question as a dedicated data challenge. The objective is to define explicit prediction tasks, datasets, simulations, and evaluation criteria in order to compare methods under controlled conditions, and to assess how reliably tumor ecosystems can be inferred from transcriptomic data.
Speaker bio
Luis Martín Peña is a doctoral researcher in bioinformatics at Université Grenoble Alpes and the Laboratoire d’informatique de Grenoble. He studies pancreatic tumour heterogeneity using spatial transcriptomics.
-
DeepStress: Stress-Testing Deep Search Agents
Abstract and speaker bio
Abstract
While search agents demonstrate impressive capabilities in multi-step question answering, their robustness to poor-quality evidence remains under-explored. This phenomenon occurs rarely in realistic benchmarks but can lead to dramatic failure in real life applications. I will present in this talk "DeepStress", a stress testing framework that controls the frequency of challenging evidence by replacing the retrieval module of search agents with a controlled synthetic environment. We use this framework to control three dimensions that can affect document reliability: trustworthiness, relevance, and factuality. Testing several search agents on HotpotQA and BrowseCompPlus, we demonstrate that agents exhibit substantial differences in their ability to handle unreliable information and propose new metrics that better document systems outcomes as well as the interactions between conflicting parametric and retrieved knowledge.
Speaker bio
Frédéric Béchet is a professor of computer science at Aix-Marseille Université, a researcher at LIS (CNRS) and an associate professor at ÉTS Montréal. He studies how computers understand spoken and written language.
-
Differentially Private Analysis of Graphs
Abstract and speaker bio
Abstract
In recent years, the use of graph analytics has shown significant value across many domains, such as social analysis and healthcare. However, the growing adoption of graph analytics corresponds to an increasing need to protect sensitive information in graph data. In this context, differential privacy has become the standard for privacy-preserving data analysis under strong mathematical guarantees. This talk provides a comprehensive overview of differentially private methods and techniques for protecting sensitive information while enabling meaningful graph analysis. We explore a variety of definitions, mechanisms, examples, and case studies to demonstrate how these methods apply across various scenarios.
Speaker bio
Javam C. Machado is a professor of computer science at the Federal University of Ceará in Brazil. His research spans database systems, privacy and the analysis of sensitive data.
-
Imen Bajar
Beneath the Face: Identity in Brain MRI
Abstract and speaker bio
Abstract
Brain MRI carries highly sensitive personal information, not only in facial features but in the unique anatomical structure of each brain, often called a “brain fingerprint.” This talk presents two studies that ask whether this identifying information remains encoded after the scan is transformed, first by defacing, then by pretrained encoders. We first evaluate defacing. Across four state-of-the-art methods (fsl_deface, PyDeface, PyFaceWipe, mri_reface) applied to T1-weighted scans from OASIS-2, a similarity-based attack using probabilistic linear discriminant analysis over FreeSurfer neuroanatomical features achieves rank-1 patient linkage with success rates of 66–73%. This shows that removing the face does not remove identity. We then ask whether sharing learned representations instead of raw scans resolves the problem. Evaluating five frozen pretrained encoders spanning different architectures, pretraining objectives and training domains on OASIS-2 and MIRIAD, under an attacker with access only to released embeddings, the corresponding public encoder, and auxiliary scans, rank-1 patient linkage reaches up to 99% on MIRIAD and exceeds 90% on OASIS-2, despite the absence of any identification objective during pretraining. The same embeddings also support recorded-sex prediction at 90.9% and 95.5% balanced accuracy. Identity is encoded in brain MRI and it survives both defacing and encoding into learned representations. New anonymization methods are needed.
Speaker bio
Imen Bajar is a doctoral researcher at INSA Lyon and ÉTS Montréal. She investigates whether people can be reidentified from brain MRI scans and their learned representations.
-
Explainability: How Do Models Learn Concepts? / Interpreto: Moving from Text to Vision
Abstract and speaker bio
Abstract
Raphael will present his paper accepted at ICML 2026: Revisiting Anisotropy in Language Transformers: The Geometry of Learning Dynamics.
Since their introduction, Transformer architectures have dominated Natural Language Processing (NLP). However, recent research has highlighted an inherent anisotropy phenomenon in these models, presenting a significant challenge to their geometric interpretation. Previous theoretical studies on this phenomenon are rarely based on the underlying representation geometry. In this paper, we extend them by providing such theoretical arguments assessing the problematic nature of this phenomenon. Furthermore, to observe geometric internal model dynamics, we apply mechanistic interpretability (MI) techniques during the model's training checkpoints rather than post-hoc, as it is commonly done in the literature. By analyzing multiple models and their checkpoints -including EuroBERT, the Pythia suite, and SmolLM2- we investigate the structure of embedding representations and their correlation with the on manifold entropy of their underlying distribution.
Hugo will present his internship work, including the extension of the Interpreto library to ViT models, as well as his thoughts on how to extend explainability and related concepts to multimodal models.
Speaker bio
Raphael Bernas is a doctoral student and Hugo de Bosschère is a master’s student at the MICS laboratory, CentraleSupélec. Both work with Fanny Jourdan. Bernas studies the geometry of language models, and de Bosschère extends interpretability tools to vision models.
-
Introduction to Machine Learning Approaches for Studying Cancer Heterogeneity
Abstract and speaker bio
Abstract
Cancer is a highly heterogeneous disease in which tumors evolve as complex multicellular ecosystems shaped by dynamic interactions between diverse cell populations. This heterogeneity is a key driver of cancer progression and treatment response, yet remains difficult to quantify and interpret, limiting our understanding of its role in oncogenesis.
At the intersection of computer science, biostatistics, and oncology, machine learning and advanced analytical methods have emerged as powerful tools to exploit high-dimensional, multimodal molecular data. This talk will introduce the key challenges, datasets, and learning approaches commonly used in life sciences to tackle cancer heterogeneity.
Magali will present ongoing projects from her team, including: (i) comprehensive benchmarks for evaluating deconvolution methods and multimodal data integration; (ii) single-cell data classification and annotation; and (iii) spatial modelling to characterize tumor ecosystems.
Beyond these methodological advances, the talk will discuss the importance of rigorous evaluation and reproducibility in computational biology, including collaborative benchmarking through scientific competitions as a framework for assessing algorithms and fostering methodological innovation.
Speaker bio
Magali Richard is a CNRS researcher in computational biology at the Laboratoire d’informatique de Grenoble. She develops methods for characterizing differences between cells within a tumour and across its spatial environment.
-
The Pareto Frontier of Randomized Learning-Augmented Online Bidding
Abstract and speaker bio
Abstract
Online algorithms make sequential decisions without knowing the future. Classical worst-case analysis provides strong guarantees against uncertainty, but can be overly pessimistic when useful information about future instances is available. Learning-augmented algorithms address this limitation by incorporating predictions, typically obtained from historical data or machine-learning models, while retaining worst-case guarantees when these predictions are inaccurate.
In this talk, I will introduce this framework through the online bidding problem, a fundamental model in which an algorithm must progressively allocate resources without knowing the amount ultimately required. I will first discuss the classical deterministic and randomized solutions and then show how access to a prediction changes the problem. The central question becomes how much an algorithm can benefit from an accurate prediction while remaining protected against arbitrarily inaccurate ones.
This tension is captured by the trade-off between consistency, which measures performance when the prediction is correct, and robustness, which controls worst-case performance. The talk will present new results characterizing the Pareto frontier between these two objectives for randomized online bidding, including a regime in which matching upper and lower bounds provide an exact characterization. The results illustrate more broadly how randomization and predictions can be combined to move beyond classical worst-case analysis without abandoning rigorous performance guarantees.
Speaker bio
Imrane Zaakour is a doctoral student at CentraleSupélec, affiliated with ILLS and the FairPlay team. He studies randomized algorithms for making sequential decisions with imperfect predictions.
-
Quantum Optimization, Quantum Annealing and QUBO
Abstract and speaker bio
Abstract
Quantum optimization—the use of quantum computing to solve combinatorial optimization problems—is developing rapidly, driven by quantum annealing systems such as D-Wave and algorithms such as QAOA for gate-based quantum hardware.
A central paradigm is Quadratic Unconstrained Binary Optimization (QUBO), closely related to the Ising model in statistical physics and now a standard formulation for quantum annealing and QAOA.
In this talk, Philippe Codognet will introduce the foundations of quantum annealing and QUBO and explain how constrained optimization and constraint satisfaction problems can be formulated in this framework. Through examples including N-queens, Magic Square, Costas Arrays, the Traveling Salesman Problem (TSP), and the Quadratic Assignment Problem (QAP), he will discuss different encoding strategies and show how modeling choices can significantly affect the performance of quantum optimization approaches.
Speaker bio
Philippe Codognet is a professor of computer science at Sorbonne Université and director of the Japanese-French Laboratory for Informatics. His research covers constraint solving and quantum approaches to combinatorial optimization.
-
Orel Mazor
Tutorial on Discrete Flow Matching
Abstract and speaker bio
Abstract
Flow matching and diffusion have emerged as state-of-the-art techniques for the generation of continuous data modalities, in particular images, audio, and video. Their strong generation performance, training stability, and flexibility have motivated their extension to discrete data, including text, graphs, and molecular sequences. This talk will provide a pedagogical introduction to flow matching for discrete data.
Speaker bio
Orel Mazor works on generative modelling at Mines Paris–PSL and Inria, with an interest in flow matching for discrete data.
-
D5P4: Partition Determinantal Point Process for Diversity in Parallel Discrete Diffusion Decoding
Abstract and speaker bio
Abstract
Discrete diffusion models are promising alternatives to autoregressive approaches for text generation, yet their decoding methods remain under-studied. Standard autoregressive search procedures, such as beam search, do not directly apply to iterative denoising, where hypotheses are complete intermediate sequences rather than left-to-right prefixes. Furthermore, existing diffusion decoding procedures only provide limited control over the diversity and coverage of retained hypotheses.
In this work, we introduce D5P4, a beam-style decoding method tailored to discrete diffusion models, which casts intermediate beam selection as MAP inference under a partitioned Determinantal Point Process. This yields a model-internal batch objective that balances quality and diversity without external verifiers. Experiments on open-ended generation, question answering, and mathematical reasoning show that D5P4 improves diversity and pass@k coverage while matching or surpassing baseline quality and fidelity. D5P4 also improves decoding efficiency, reducing post-forward latency and peak memory while scaling to large candidate pools.
Speaker bio
Vincent Gripon is a professor at IMT Atlantique and a member of Lab-STICC. His research interests include neural network compression, learning from few examples and foundation models for EEG.
-
I.i.d. Prophet Inequalities with Discounted Rewards: As Hard as the Non-i.i.d. Case
Abstract and speaker bio
Abstract
We study prophet inequalities with discounted rewards, where i.i.d. base rewards are multiplicatively discounted over time. Our main message is that even this structured and arbitrarily weak form of nonstationarity can erase the classical advantage of the stationary i.i.d. setting. Focusing on single-quantile threshold policies, we show that the competitive ratio transitions from the classical 1-1/e guarantee to a fundamental 1/2 barrier as discounting accumulates over many phases in a canonical regime with a common-decay factor and equal-length phases. We further show that, in the same regime, the 1/2 barrier persists even for arbitrary stopping rules. Consequently, i.i.d. base rewards under discounting can be as hard as the fully non-i.i.d. case. On the algorithmic side, we design single-quantile threshold rules that attain the tight bounds by calibrating acceptance decisions to an effective horizon induced by discounting, and we extend this calibration to heterogeneous decay factors and unequal phase lengths. We further show that a similar discontinuous breakdown persists in an infinite-horizon continuous-decay benchmark, where arbitrarily weak decay collapses the stationary benchmark from 1 to 1/2.
Speaker bio
Jung-hun Kim is a postdoctoral researcher on the FairPlay team at CREST, ENSAE Paris. He studies optimal stopping and the guarantees achievable when decisions must be made sequentially.
-
Towards the Anonymization of Masked Language Modeling
Abstract and speaker bio
Abstract
Rapid advances in Natural Language Processing (NLP) have revolutionized many fields, including healthcare. However, these advances raise significant privacy concerns, especially when pre-trained models, fine-tuned and specialized on sensitive data, can memorize and then expose and regurgitate personal information.
This paper presents a privacy-preserving language modeling approach to address the problem of anonymization of language models, and thus promote their sharing.
Specifically, we propose a Masked Language Modeling (MLM) methodology to specialize a BERT-like language model that prevents the model from memorizing direct and indirect identifying information present in the training data.
We comprehensively evaluated our approach on several models using a medical dataset and a corpus of legal texts, and compared it to different baselines.
Our results indicate that by avoiding memorizing both direct and indirect identifiers during model specialization, our masked language modeling schemes offer a good tradeoff for maintaining high privacy while retaining high utility.
Speaker bio
Antoine Boutet is a faculty member at INSA Lyon and works with the Inria Privatics team. He studies security and privacy in systems that collect, share or learn from personal data.
-
Real-Time Optimisation for Online Learning in Auctions
Abstract and speaker bio
Abstract
In display advertising, a small group of sellers and bidders face each other in up to 10¹² auctions a day. At this scale, revenue maximisation is a high-value problem for sellers, and the lack of competition means they can approach it via learning the monopoly price. However, because these auctions are online the learning algorithm must be real time, contrary to existing methods. We will discuss how to construct updates which are constant in time and memory, mixing some ideas from stochastic gradient descent and simulated annealing.
Speaker bio
Lorenzo Croissant is a researcher at Universitat Pompeu Fabra. His work brings together online learning, stochastic optimization and auctions.
-
Concept-based Explanations for Language Models (part of Mechanistic Interpretability)
Abstract and speaker bio
Abstract
This presentation begins with an introduction to concept-based explanations: what they are, the different families of methods, and how to obtain them. We then focus on post-hoc, unsupervised concept-based approaches that leverage dictionary learning. Then I will present some contributions, an evaluation metric, ConSim, and the open-source library Interpreto. Finally, I will describe ongoing works on contrastive concept-based explanations, probing concepts’ geometry, and evaluating which types of concepts can be interpreted.
Speaker bio
Antonin Poché is a doctoral researcher affiliated with IRT Saint Exupéry and IRIT. He develops and evaluates concept-based methods for interpreting language models.
-
Learning Autoregressive Image Generation Orders via Variational Inference
Abstract and speaker bio
Abstract
What's the right order to generate an image? Autoregressive image models default to a raster order (left to right), which is convenient but, unlike text's natural reading order, isn't an obvious choice. We set out to learn a better order using a variational inference approach: an order encoder receives the full image as input and proposes the order in which a causal decoder should generate the tokens. While the same framework can discover good orders in other domains, it wasn't helpful in ours (class-conditional image generation). We trace this back to an information mismatch between the encoder and the decoder, and identify the conditions under which variational order learning can be expected to work.
Speaker bio
Amin Sghaier is a master’s student at ILLS studying how autoregressive models learn the order in which to generate the parts of an image.
-
Vision and Mental Imagery
Abstract and speaker bio
Abstract
A central question in cognitive neuroscience is whether imagery and visual perception rely on the same underlying representations and mechanisms. A common view is that the mental images we generate internally closely resemble the representations engaged during actual vision. If this is true, one would expect strong links between the quality of mental imagery and perceptual performance. However, our recent work suggests that this relationship is more complex than traditionally assumed. Across several studies, we found limited evidence that subjective vividness of mental images is systematically related to visual recognition or discrimination abilities. Even when the tasks were designed to maximize overlap between what participants imagined and what they later perceived, the association remained weak. These findings suggest that subjective vividness may not be a straightforward index of the representational quality shared between imagery and perception. This led us to explore vividness more directly. To better understand what drives vividness judgments, we developed a large-scale database of vividness ratings for natural scenes. By collecting a very large number of ratings across a broad image set, this work aims to identify which visual characteristics make certain images easier to imagine vividly than others. In parallel, computational modeling approaches are being used to predict vividness from image features, opening the possibility of isolating the visual properties that support strong mental imagery. At the same time, we are developing alternatives to subjective vividness ratings as a way to compare imagery and vision more directly at the representational level. One promising approach uses behavioral similarity spaces: instead of asking participants how vivid an image feels, we compare the structure of relationships among imagined and perceived stimuli. This work provides evidence that the representational geometry of imagery aligns substantially with that of vision, beyond what can be explained by semantic descriptions alone. In other words, imagery and perception may share internal structure even when simple vividness judgments fail to capture it. A complementary line of work investigates shared mechanisms using psychophysical tools such as visual adaptation. Here, the question is whether imagining a stimulus can bias subsequent perception in the same way that actual visual exposure does. Early evidence suggests that imagined stimuli can indeed produce measurable aftereffects, even at relatively high levels of visual processing, offering a powerful tool to probe the overlap between imagery and perception. Taken together, these projects suggest a nuanced picture: mental imagery and vision do appear to share representational and mechanistic components, but this overlap is not always reflected in standard vividness ratings. Moving beyond subjective reports toward representational and psychophysical measures may therefore provide a more precise understanding of how the mind’s eye relates to vision itself.
Speaker bio
Frédéric Gosselin is a professor of psychology at Université de Montréal. He investigates the mechanisms that visual perception and mental imagery have in common.
-
Generative Models and Deep Priors for Image and Video Restoration and Editing
Abstract and speaker bio
Abstract
Modern algorithms for image and video restoration and editing now rely on the impressive capabilities of powerful neural networks, in particular generative models. By generating examples of image data, we are training a neural network to implicitly discover the space of realistic images, and this knowledge, often referred to as a "Deep Prior", can subsequently be employed for the purposes of restoration and editing. In this talk, I will present three topics which employ such an approach.
The first work focuses on video inpainting, that is, filling in missing or damaged regions in videos. We propose an approach based on diffusion models, a family of particularly powerful generative models that rely on the progressive inversion of a noising process. However, the large size of these models, in terms of the number of parameters, makes them difficult to use, especially for high-dimensional data such as videos. Therefore, in this work, we propose a "frugal" approach to video inpainting, based on the assumption of self-similarity in videos, i.e., the presence of redundant content. We obtain results that are equivalent or superior to state-of-the-art models, while using much more compact models, by one or more orders of magnitude.
In the second work, we use the projected gradient descent algorithm to solve inverse problems, such as super-resolution and image inpainting, replacing the projection step with a deep neural network (the deep prior). In particular, we introduce a Stochastic Orthogonal Regularization ("SOR") of the network, which allows control over the convergence rate of the projected gradient descent algorithm, and empirically improves the quality of the solutions. I will show quantitative and qualitative experiments which illustrate this, particularly when the degradation operator is more severe.
Finally, I will present a series of works which employ generative models for image editing, with the goal of modifying semantic content such as the expression of a face in images. These methods structure the latent spaces of generative models to correspond to the desired semantic attributed, enabling simple and controllable editing.
Speaker bio
Alasdair Newson is an associate professor at Télécom Paris. He develops computer vision and generative modelling methods for analysing, restoring and editing images and video.
-
Toward a lingua franca of the mind: shared representations in vision and language
Abstract and speaker bio
Abstract
Are there such things as universal representations? In this talk, I will present recent work showing that embeddings from large language models align closely with high-level visual representations measured with fMRI (Natural Scenes Dataset; NSD). Extending this framework, new results demonstrate that vision and language share a joint representational space that generalises across modalities. I will also introduce NSD-EEG, a new dataset pairing natural scenes with high-density EEG, and showcase a novel spatiotemporal fusion method that enables exploring brain processing of natural scenes with unprecedented spatiotemporal precision. Together, these advances highlight a path toward richer Bio-AI interfaces bridging language, vision, and neural signals, and shared universal representations as a common objective of sensory processing.
Speaker bio
Ian Charest is a professor of psychology at Université de Montréal. He combines neuroimaging and artificial intelligence to investigate how the brain represents what we see and hear.
-
Centering People in the NLP Pipeline: A Sociotechnical Perspective on NLP Technology Design and Evaluation
Abstract and speaker bio
Abstract
Natural language processing (NLP) technologies are increasingly ubiquitous. Yet they can be harmful or behave undesirably; they can benefit people unequally, shift people’s beliefs, and erode people’s agency. In this talk, I argue that given the contextual and open nature of language and emerging generative AI systems, developing equitable and empowering NLP technologies requires a sociotechnical perspective. I will illustrate two places in the NLP pipeline that this perspective informs: first, design goals—how technologies ought to behave—and second, evaluation—assessing their capabilities, behaviours, and impacts. I will first describe work on object recognition and natural language generation systems that shows that people’s expectations and preferences for system behaviours are varied and conflicting, raising questions about how to decide what constitute “fair” or “good” system behaviours. I will then describe work analyzing NLP benchmark datasets constructed to measure stereotyping, which uncovers a range of pitfalls threatening these benchmarks’ validity and provides a foundation for better assessing and building benchmarks. Together, this sociotechnically-informed work advances the development of NLP technologies that meaningfully realize their intended benefits in their deployment contexts.
Speaker bio
Su Lin Blodgett is a principal researcher in the FATE group at Microsoft Research Montréal. She examines how the design and evaluation of language technologies affect the people who use them.
-
Adversarial Perspectives on Local Differential Privacy: Attacks, Auditing, and Protocol Design
Abstract and speaker bio
Abstract
Local Differential Privacy (LDP) has emerged as a practical paradigm for privacy-preserving data analytics, enabling strong guarantees without relying on a trusted server. However, despite its formal definitions, recent research has shown that LDP mechanisms are vulnerable to adversarial inference, with attacks capable of reconstructing or inferring user data even under ε-LDP guarantees. This talk presents an adversarial perspective on LDP, revealing both its weaknesses and opportunities. The talk first examines how reconstruction and inference attacks expose vulnerabilities that remain hidden when considering only the theoretical parameter ε. These very attacks can then be repurposed as auditing tools, allowing the statistical estimation of the effective privacy loss of deployed protocols and revealing discrepancies between theoretical guarantees and real-world leakage. Building on these insights, we will introduce a framework for refining and designing new LDP protocols through multi-objective optimization, balancing privacy, utility, and robustness to attacks. The resulting protocols achieve more favorable trade-offs, substantially reducing adversarial success rates while maintaining practical accuracy. Overall, the talk bridges the gap between theory and practice, providing concrete strategies for designing attack-aware, auditable, and adaptive LDP mechanisms.
Speaker bio
Héber Hwang Arcolezi is an assistant professor at ÉTS Montréal. His research focuses on differential privacy, attacks and auditing, and responsible AI.
-
Toward Understanding the Generalization of Flow Matching
Abstract and speaker bio
Abstract
Modern deep generative models can now produce high-quality synthetic samples that are often indistinguishable from real training data. A growing body of research aims to understand why recent methods, such as diffusion and flow matching techniques, generalize so effectively. Among the proposed explanations are the inductive biases of deep learning architectures and the stochastic nature of the conditional flow matching loss. In this work, we rule out the noisy nature of the loss as a key factor driving generalization in flow matching. First, we empirically show that in high-dimensional settings, the stochastic and closed-form versions of the flow matching loss yield nearly equivalent losses. Then, using state-of-the-art flow matching models on standard image datasets, we demonstrate that both variants achieve comparable statistical performance, with the surprising observation that using the closed-form can even improve performance.
Speaker bio
Quentin Bertrand is a researcher at Inria in Lyon. He studies how deep generative models learn from data and how they generalize beyond their training examples.
-
Learning Vision-Language Uncertainties for Failure Prediction
Abstract and speaker bio
Abstract
Reliable Uncertainty Quantification (UQ) and failure prediction remain open challenges for Vision-Language Models (VLMs). We introduce ViLU, a new vision-language uncertainty quantification framework that contextualizes uncertainty estimates by leveraging all task-relevant textual representations.
ViLU builds an uncertainty-aware multi-modal representation by integrating the visual embedding, the predicted textual embedding, and an image-conditioned textual representation via cross-attention.
Unlike traditional UQ methods based on loss prediction, ViLU trains an uncertainty predictor as a binary classifier to distinguish correct from incorrect predictions using a weighted binary cross-entropy loss, making it loss-agnostic and particularly suitable for post-hoc settings where only vision and text embeddings are available.
Extensive experiments on diverse datasets demonstrate significant gains over state-of-the-art failure prediction methods.
Speaker bio
Marc Lafon works at the Institut des systèmes intelligents et de robotique (ISIR), Sorbonne Université. His research examines how uncertainty estimates can identify likely failures in vision-language models.
-
When Pragmatic AI Agents Misalign: Safety Risks in Multi-Agent AI Systems — A Focus on Deceptive Behavior
Abstract and speaker bio
Abstract
As AI systems increasingly interact autonomously, they form multi-agent systems whose collective behavior can diverge in unexpected and potentially harmful ways. Such systems will soon permeate economic, military, and critical infrastructure domains, making risk assessment and mitigation urgent.
Building on the Rational Speech Act (RSA) framework—a quantitative model of recursive reasoning based on beliefs and intentions—we study scenarios where an agent strategically manipulates communication to exploit another agent while hiding this behavior under the guise of cooperation.
A key question emerges: under what conditions can the exploited agent detect that its counterpart is no longer aligned with the assumed shared goal?
Speaker bio
Federica Granese is a researcher with the Marianne team at the Inria Centre at Université Côte d’Azur. She studies the safety and reliability of machine learning systems.
-
THUNDER: Tile-level Histopathology image UNDERstanding benchmark
Abstract and speaker bio
Abstract
Progress in a research field can be hard to assess, in particular when many concurrent methods are proposed in a short period of time. This is the case in digital pathology, where many foundation models have been released recently to serve as feature extractors for tile-level images, being used in a variety of downstream tasks, both for tile- and slide-level problems. Benchmarking available methods then becomes paramount to get a clearer view of the research landscape. In particular, in critical domains such as healthcare, a benchmark should not only focus on evaluating downstream performance, but also provide insights about the main differences between methods, and importantly, further consider uncertainty and robustness to ensure a reliable usage of proposed models. For these reasons, we introduce THUNDER, a tile-level benchmark for digital pathology foundation models, allowing for efficient comparison of many models on diverse datasets with a series of downstream tasks, studying their feature spaces and assessing the robustness and uncertainty of predictions informed by their embeddings. THUNDER is a fast, easy-to-use, dynamic benchmark that can already support a large variety of state-of-the-art foundation, as well as local user-defined models for direct tile-based comparison. In this paper, we provide a comprehensive comparison of 23 foundation models on 16 different datasets covering diverse tasks, feature analysis, and robustness.
Speaker bio
Pierre Marza is a postdoctoral researcher in the biomathematics team at MICS, CentraleSupélec. He develops computer vision and deep learning methods for digital pathology.
-
MLPerf Storage: A Benchmark for Sustainable Storage-Aware ML Systems Design
Abstract and speaker bio
Abstract
Machine learning (ML) workloads are increasingly limited by data loading and storage performance, yet storage systems remain underrepresented in most ML benchmarking efforts. MLPerf Storage—a new benchmark developed under MLCommons—fills this gap by enabling accurate evaluation of storage performance for ML workloads without requiring GPUs.
By replacing GPU processing time with calibrated sleep intervals, MLPerf Storage simulates realistic dataloader and dataset behaviors across various accelerator types, all while dramatically reducing resource usage. This innovative approach allows vendors and system designers to tune storage-GPU ratios, prototype new system architectures, and evaluate storage solutions in isolation—all with minimal energy and hardware cost.
From a systems research perspective, MLPerf Storage opens new avenues for reproducible experiments, design-space exploration, and hardware/software co-design. It supports fair comparisons across storage architectures and allows researchers to study the impact of data pipeline optimizations on overall system efficiency. Ongoing work with MLPerf Power further integrates power measurements, reinforcing the benchmark's value as a tool for sustainable systems research.
This talk will present the benchmark's design, its relevance for sustainable ML system design, and insights from recent submission rounds—making the case for storage-aware ML system optimization as an overlooked lever in improving both performance and sustainability.
Speaker bio
Oana Balmau is an assistant professor in McGill University’s School of Computer Science, where she leads the DISCS Lab. She co-founded MLPerf Storage and studies data management and storage systems.
-
Explainability and Bias Evaluation in Large Language Models
Abstract and speaker bio
Abstract
In this talk, I will first present a study on evaluating gender bias in Large Language Models (LLMs) for the Machine Translation task.
Then, I will present my research on concept-based explainability applied to LLMs, a line of work that intersects with what is often referred to as mechanistic interpretability. I will also discuss how such methods can be evaluated.
Finally, I will introduce Interpreto, an open-source Python library we are developing to provide a unified framework for explainability across NLP models.
Speaker bio
Fanny Jourdan studies gender bias and concept-based explanations in large language models. Her work includes developing Interpreto, an open-source library for interpreting NLP models.
-
Computational approaches to characterize cellular and spatial heterogeneity in cancer
Abstract and speaker bio
Abstract
Cancer is a highly heterogeneous disease, with each tumor evolving as a multicellular, self-organized system. Tumors comprise diverse cell types of distinct origins, interacting dynamically to shape a complex ecosystem. This cellular heterogeneity is a major driver of cancer progression, yet remains challenging to observe, quantify, and interpret. Our limited ability to accurately estimate it continues to hamper a comprehensive understanding of oncogenesis.
At the interface of bioinformatics, biostatistics, and oncology, our work develops computational strategies to analyze high-dimensional, multimodal molecular data, including single-cell and spatial transcriptomic datasets. These tools aim to disentangle tumor complexity and reveal its functional implications.
In this talk, I will present approaches we have designed to characterize tumor heterogeneity. I will illustrate them with two examples: (i) the construction of single-cell atlases to describe cellular heterogeneity in pancreatic adenocarcinoma, and (ii) the analysis of spatial organization to predict how heterogeneity shapes tumor evolution.
Finally, I will highlight our efforts to foster collaborative benchmarking and evaluation of computational algorithms through data challenge frameworks. By enabling transparent comparison of methods, such initiatives foster reproducibility and accelerate the translation of methodological research into biological discovery.
Speaker bio
Magali Richard is a CNRS researcher in computational biology at the Laboratoire d’informatique de Grenoble. She develops methods for characterizing differences between cells within a tumour and across its spatial environment.
-
Video-based fall risk prediction using heterogeneous and multimodal data
Abstract and speaker bio
Abstract
This talk will present the first results of a multi-disciplinary project aiming at predicting fall risk in healthy older people. As falls in the elderly are a significant problem, a novel paradigm is being evaluated. A non-invasive protocol will be detailed, and the first results will be presented, followed by a discussion.
Speaker bio
Anaïs Chaumeil studies human movement and fall risk in older adults. Her research brings together biomechanics, video-based motion analysis and machine learning.
-
A Journey through Deep Neural Network Debiasing
Abstract and speaker bio
Abstract
This talk will explore the area of debiasing for deep neural networks, starting from the original problem setup in image classification and its popular variants. The focus will be on model debiasing, including both bias-supervised approaches (e.g., EnD and ε-SupInfoNCE) and bias-unsupervised methods. The talk will conclude with strategies for bias discovery in unsupervised settings and approaches for mining debiased architectures from biased models.
Speaker bio
Enzo Tartaglione is an associate professor at Télécom Paris, where he leads the Multimedia team and holds a Hi! PARIS chair. He studies how to identify and reduce bias in neural networks, protect privacy during learning and compress models.
-
 Éric Gaussier
AI research at MIAI Grenoble and opportunities for research visits
Research overview and speaker bio
Research overview
Éric Gaussier introduced the research teams and projects at Grenoble’s Multidisciplinary Institute in Artificial Intelligence (MIAI). The visit gave ILLS researchers a chance to discuss shared interests and opportunities for master’s and doctoral students to spend time with teams in Grenoble.
Speaker bio
Éric Gaussier is a professor of computer science at Université Grenoble Alpes. At the time of this seminar, he directed MIAI in Grenoble.
-
Single location regression and attention-based models
Abstract and speaker bio
Abstract
Attention-based models, such as Transformer, excel across various tasks but lack a comprehensive theoretical understanding, especially regarding token-wise sparsity and internal linear representations. To address this gap, we introduce the single-location regression task, where only one token in a sequence determines the output, and its position is a latent random variable, retrievable via a linear projection of the input. To solve this task, we propose a dedicated predictor, which turns out to be a simplified version of a non-linear self-attention layer. We study its theoretical properties, by showing its asymptotic Bayes optimality and analyzing its training dynamics. In particular, despite the non-convex nature of the problem, the predictor effectively learns the underlying structure. This work highlights the capacity of attention mechanisms to handle sparse token information and internal linear structures.
This is a joint work with Pierre Marion, Gérard Biau and Raphaël Berthier.
Speaker bio
Claire Boyer is a professor at the Laboratoire de mathématiques d’Orsay, Université Paris-Saclay. She studies the mathematical foundations of machine learning. During her visit to ILLS, she gave this blackboard talk on what an attention layer can learn from a single informative token.
-
Adversarial Robustness and Privacy Measurements using Hypothesis-tests
Abstract and speaker bio
Abstract
ML theory usually considers model behaviour in expectation. In practical AI deployments however, we often expect models to be robust to adversarial perturbations, in which a user applies deliberate changes to an input to influence the prediction of a target model. For instance, such attacks have been used to jailbreak aligned foundation models out of their normal behaviour. Given the complex models that we now deploy, how can we enforce such robustness properties while keeping model flexibility and utility?
I will present recent work on Adaptive Randomized Smoothing (ARS), an approach we developed to certify the predictions of test-time adaptive models against adversarial examples. ARS extends the analysis of randomized smoothing using f-Differential Privacy, to certify the adaptive composition of multiple steps during model prediction. We show how to instantiate ARS on deep image classification to certify predictions against adversarial examples of bounded L∞ norm.
If time permits, I will also connect f-Differential Privacy's hypothesis testing view of privacy to the audit of data leakage in large AI models. Specifically, I will discuss a new data leakage measurement technique we developed, that does not require access to in-distribution non-member data. This is particularly important in the age of foundation models, often trained on all available data at a given time. It is also related to recent efforts in detecting data use in large AI models, a timely question at the intersection of AI and intellectual property.
Speaker bio
Mathias Lécuyer is an assistant professor at the University of British Columbia. He develops methods with provable guarantees for machine learning, including randomized smoothing against adversarial examples and tools for tracking privacy loss.
-
 Michele Orrù
Building, and building on, authentication systems for user privacy and anonymity
Abstract and speaker bio
Abstract
We will explore some of the core principles of modern cryptography, taking the case of non-interactive zero-knowledge arguments. After an overview of the state-of-the-art research and a grip of the hardness of some protocols, we will see use cases that are driving the practical deployment of zero-knowledge proofs in real-world applications.
Speaker bio
Michele Orrù is a CNRS researcher in cryptography and security. His research covers zero-knowledge proofs, anonymous credentials and confidential transactions. He contributes to the arkworks cryptography libraries.
-
Leonhard Grosse
Pointwise Maximal Leakage - Privacy Guarantees and Mechanisms towards Modern Applications
Abstract and speaker bio
Abstract
Modern data processing methods increasingly subject individuals' sensitive personal data to the risk of malicious inference by big data service providers or third parties. To mitigate this risk, provable privacy guarantees for data processing systems have emerged as a promising approach. These guarantees are based on an underlying privacy measure that aims to efficiently and precisely measure a notion of privacy that should be aligned with legal definitions. In recent years, differential privacy (DP) has become the de facto standard measure used for providing stringent guarantees. However, it can be argued that DP guarantees cannot rule out the possibility of privacy violations for databases with correlated entries. Further, the strict definition of DP based on neighboring databases poses a challenge in learning systems, as useful privacy guarantees with DP often severely diminish model performance. These shortcomings motivate the development of measures that quantify privacy in a Bayesian framework. In this talk, we will introduce a recently proposed Bayesian measure called pointwise maximal leakage (PML). PML is based on two equivalent explicit threat models, and enables clear inferential guarantees that can rule out the possibility of general inference attacks. We develop the measure from ground up, and show how it is obtained from the underlying threat models. Further, we will outline how the inferential nature of the measure can be used to quantitatively interpret the privacy parameter in PML guarantees. Finally, we will show how the measure can be used to design discrete data sanitization mechanisms that improve data utility compared to DP.
Speaker bio
Leonhard Grosse studies information privacy at KTH Royal Institute of Technology in Stockholm. His work uses models of what an observer can infer about an individual to design privacy mechanisms and quantify their guarantees.
-
Machine Learning with Scarce Annotations: Applications in Speech Processing, Bioacoustics, and Underwater Imaging
Abstract and speaker bio
Abstract
This talk will provide an overview of our research tackling the challenge of working with minimal or no human annotations. I will begin by discussing our initial work on computational models of music perception, which led to my interest in textless speech processing. I will demonstrate how self-supervised learning and weak supervision techniques have been pivotal in addressing questions related to handwritten and acoustic unit discovery, modeling intelligibility at the microscopic level, and developing spoken language models.
Next, I will present our studies on bioacoustics, where we train deep learning models on audio recordings with limited annotations. We utilize the spatialization of multi-channel data and unsupervised clustering to significantly reduce the need for human annotation. This approach has enabled us to gain insights into hard-to-study species like sperm whales and to characterize the long-term evolution of the fin whale song.
Finally, I will cover our latest work in computer vision, specifically in the context of ocean exploration and visual relocalization of underwater unmanned vehicles. I will highlight the challenges we face in tasks such as pose estimation and color restoration, where the lack of ground truth references and the unique properties of light transport in underwater environments make these problems particularly intriguing.
Throughout the talk, I will illustrate how our use of advanced machine learning techniques and innovative approaches has allowed us to make significant strides in these diverse fields, despite the scarcity of human annotations.
Speaker bio
Ricard Marxer is a professor at the Université de Toulon. At LIS, he leads the DYNI team studying the dynamics of information. His group uses self-supervised learning to study speech, whale vocalizations and underwater imagery when human annotations are scarce.
-
Robustness in AI
Abstract and speaker bio
Abstract
The recent success of AI and deep learning still faces important robustness issues. In this talk, I will discuss open problems and solutions for improving i) uncertainty quantification, ii) direct optimization of rank losses, and iii) limiting mistake severity.
Speaker bio
Nicolas Thome is a professor at Sorbonne Université. He studies machine learning for vision, time series and robotics, with a particular interest in how models estimate uncertainty and how to limit the severity of their errors.
-
Learning-augmented algorithms
Abstract and speaker bio
Abstract
I will give a quick overview of a relatively nascent, but already very prominent field of online computation, in which the algorithm is enhanced by some machine-learned prediction. I will discuss challenges in modeling, devising, and analyzing such algorithms, and highlight some current and future directions for further work.
Speaker bio
Spyros Angelopoulos is a CNRS researcher at LIP6, Sorbonne Université. He designs and analyses algorithms for decision-making under uncertainty, including online algorithms that use machine-learned predictions.
-
WikiFactDiff: A Large, Realistic, and Temporally Adaptable Dataset for Atomic Factual Knowledge Update in Causal Language Models
Abstract and speaker bio
Abstract
The factuality of language models deteriorates over time since events subsequent to their training are unknown to them. One way to keep these models up to date could be factual update of atomic facts. To study this task, we present WikiFactDiff, a dataset that contains changes between two dates as a set of simple facts, in RDF format, divided into three categories: facts to learn, facts to keep and obsolete facts. Indeed, WikiFactDiff was built by comparing the state of Wikidata on January 4, 2021 and February 27, 2023. These facts are verbalized in order to allow the execution of update algorithms and their evaluation. Unlike existing datasets, WikiFactDiff represents a realistic editing framework that involves various scenarios, including replacements, archiving, and inserting new entities.
Speaker bio
At the time of the talk, Hichem Ammar Khodja was a doctoral student at Orange Innovation and Aix-Marseille Université, Gwénolé Lecorvé was a researcher at Orange Innovation, and Alexis Nasr was a professor at Aix-Marseille Université. Their joint presentation examined how to update facts stored in language models.
-
Generative Models for exploring Digital Humanities archives and research activities in NLP at Orange
Abstract and speaker bio
Abstract
The talk will present Research activities in NLP at Orange with a focus on a recent experiment of domain adaptation of Large Language Models for the Telecom domain, as well as a quick overview of the joint work between Orange and Aix Marseille University on Low-Rank Adaptation of LLMs and the use of generative models for exploring Digital Humanities archives.
Speaker bio
Géraldine Damnati is a researcher at Orange Innovation in Lannion, France. Her work in natural language processing includes customer relations and knowledge management. At the time of the talk, Elie Antoine and Loïc Fosse were doctoral students studying language processing through a collaboration between Orange and Aix-Marseille Université.
-
A2CiD2: Accelerating Asynchronous Communication in Decentralized Deep Learning
Abstract and speaker bio
Abstract
I will discuss a principled algorithm to accelerate communication for training a Deep Learning model using an asynchronous, decentralized approach. Traditional synchronous methods encounter significant communication bottlenecks at scale. To address this, we introduce A2CiD2, a principled asynchronous, randomized, gossip-based optimization algorithm. This approach leverages continuous local momentum, enabling workers to process mini-batches continuously without downtime. Our method accelerates communication without additional costs, outperforming previous decentralized baselines. The theoretical analysis demonstrates accelerated communication rates compared to existing asynchronous approaches. Empirical results both on poorly (e.g., ring graph) and well connected networks, on ImageNet with 64 asynchronous workers (A100 GPUs), showcase substantial reductions in communication costs.
Speaker bio
Édouard Oyallon is a CNRS researcher at ISIR, Sorbonne Université. His research focuses on large-scale decentralized learning and geometric deep learning. He previously taught at CentraleSupélec and earned a doctorate in applied mathematics at the École normale supérieure.
-
Cyclic Data Parallelism for Efficient Parallelism of Deep Neural Networks
Abstract and speaker bio
Abstract
Training large deep learning models requires parallelization techniques to scale. In existing methods such as Data Parallelism or ZeRO-DP, micro-batches of data are processed in parallel, which creates two drawbacks: the total memory required to store the model's activations peaks at the end of the forward pass, and gradients must be simultaneously averaged at the end of the backpropagation step. We propose Cyclic Data Parallelism, a novel paradigm shifting the execution of the micro-batches from simultaneous to sequential, with a uniform delay. At the cost of a slight gradient delay, the total memory taken by activations is constant, and the gradient communications are balanced during the training step. With Model Parallelism, our technique reduces the number of GPUs needed, by sharing GPUs across micro-batches. Within the ZeRO-DP framework, our technique allows communication of the model states with point-to-point operations rather than a collective broadcast operation. We illustrate the strength of our approach on the CIFAR-10 and ImageNet datasets.
Speaker bio
At the time of the talk, Louis Fournier was a doctoral student at ISIR, Sorbonne Université. He studied how to distribute neural network training across GPUs while controlling memory use and communication costs.
-
Decentralized machine learning as an enabler of decentralized recommender systems
Abstract and speaker bio
Abstract
There is a strong momentum towards data-driven services at all layers of society and industry. This started from large scale web-based applications such as Web search engines (e.g., Google, Bing), social networks (e.g., Facebook, TikTok, Twitter, Instagram) and recommender systems (e.g., Amazon, Netflix) and is becoming increasingly pervasive thanks to the adoption of handheld devices and the advent of the Internet of Things. Recent initiatives such as Web 3.0 are coming with the promise of decentralizing such services for empowering users with the ability to gain back control over their personal data, and prevent a few economic actors from over concentrating decision power. However, decentralizing online services calls for decentralizing the machine learning algorithms on which they heavily rely. In this presentation I will present the work we carry out in the team towards decentralizing machine learning and how we apply it to recommender systems. I will particularly focus on two aspects, namely the impact of decentralization on personalization and on privacy.
Speaker bio
Sonia Ben Mokhtar is a CNRS research director at LIRIS in Lyon. At the time of this joint ILLS–STARaCom seminar at McGill, she led the distributed systems and information retrieval group (DRIM). She studies how distributed systems can remain resilient and protect personal data.
-
Variational Audio-Visual Representation Learning
Abstract and speaker bio
Abstract
Learning robust and powerful representations is at the core of many problems in multimedia, including content representation, multi-modal fusion, social signals, etc. While the supervised and self-supervised learning paradigms showed great progress in many applications, the learned representations are strongly tailored to one application or domain, and their adaptation to a different scenario or dataset might require large amounts of data, not always available. Deep probabilistic models provide an opportunity to exploit various unsupervised mechanisms that enable several interesting properties. First, they can combine with other deep or shallow probabilistic models within the same methodological framework. Second, they can include unsupervised mixture mechanisms useful for modality and/or model selection on-the-fly. Third, they are naturally suitable not only for unsupervised learning, but also for unsupervised adaptation, thus overcoming a potential domain shift with few data. In this talk, we will discuss the methodology of deep probabilistic models, i.e. variational learning, and showcase their interest for multi-modal applications with auditory and visual data of human activities (speech and motion).
Speaker bio
Xavier Alameda-Pineda gave this joint ILLS–STARaCom seminar at McGill as a researcher in the Perception team at Inria Grenoble Rhône-Alpes and Université Grenoble Alpes. He combines audio and visual signals to study human activity, scene understanding and human–robot interaction.
-
Scheduling task graphs to reduce data movement
Abstract and speaker bio
Abstract
In this talk, we will first present the growing problem of data movements in high performance computing, as well as different models that were introduced to study it. Then, we will present some work on modeling complex computations as task graphs, and how to schedule them in order to reduce the amount of memory used and the amount of input/output operations, with application to linear algebra and neural network training.
Speaker bio
Loris Marchal is a CNRS researcher at the Laboratoire de l’informatique du parallélisme in Lyon. He studies how to schedule high-performance computations when memory, data transfers and input/output are limiting resources.
-
Information Analysis and Methods for Representation Learning and Data-Driven Structural Detection
Abstract and speaker bio
Abstract
Machine learning and Information Theory are two broad research areas with strong connections. In this presentation, we will cover two topics that explore the use of information-theoretic measures in learning. On the first topic, we will present results that show how adequate the adoption of mutual information is for predicting the operational quality of a transformation (or encoder) in classification. These results offer new insights into adopting information measures in machine learning, like mutual information and cross-entropy. For the second topic, we will discuss the idea of information sufficiency, representing a model's latent structure, and explore a non-parametric data-driven method to detect this type of structure from data. We will focus on the learning-decision task of testing independence using a non-parametric mutual information estimator. We present non-asymptotic and asymptotic results that support the advantage of this approach and elaborate on applications for learning data structure and model-change detection.
Speaker bio
At the time of the seminar, Jorge F. Silva was an associate professor of electrical engineering at the Universidad de Chile and a principal investigator at the Advanced Center for Electrical and Electronic Engineering in Valparaíso. His research connects information theory, representation learning and statistical signal processing.















Past events
There are no past events to display.
-
AI4H 2026 — Artificial Intelligence for Healthcare Applications
ILLS, ÉTS and LAMIH co-organized this three-day workshop. Researchers and clinicians discussed how AI can guide rehabilitation, help surgeons interpret images during operations, and reveal patterns in brain scans.
View the workshop programme -
ILLS Workshop at Bellairs
ILLS researchers met at McGill University’s Bellairs Research Institute to discuss machine learning on graphs and statistical signal processing.
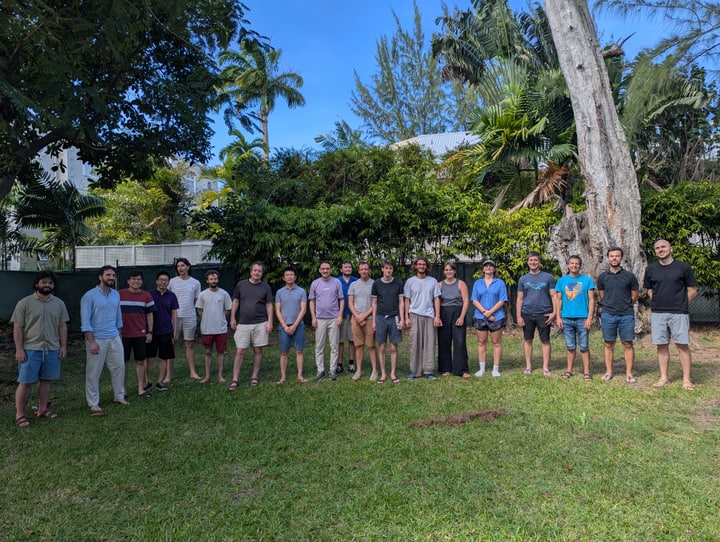
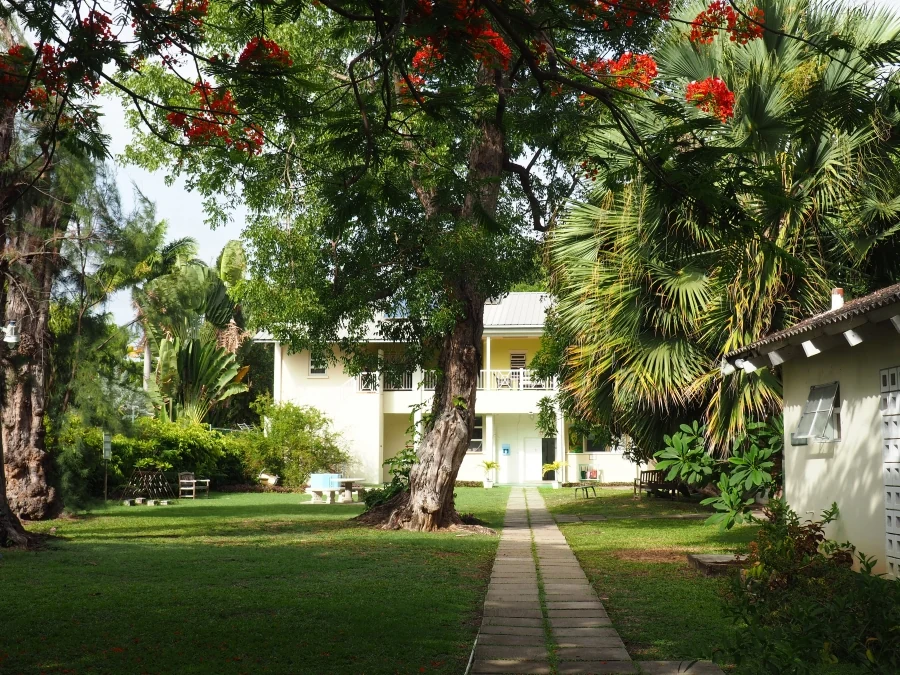
Photo © McGill University -
18th Scheduling for Large-Scale Systems Workshop
The workshop explored how to allocate GPUs among competing jobs, distribute the work of training a model, and account for energy use when scheduling computations.
Workshop programme and slides -
Featured workshop
France–Québec workshop on language processing in the age of generative AI
ILLS and Mila co-organized this three-day meeting with CNRS, GDR TAL, FRQNT and IVADO. Researchers from France and Québec explored how language models handle languages with little training data, what human language development can teach us about AI, and when people rely too heavily on conversational systems.
Explore the programme at MilaProgramme at a glance
- 1 October
- Generative models and multilingual NLP
- 2 October
- How humans and machines learn language
- 3 October
- Conversational AI and its impact on society
Organizing committee
Pablo Piantanida, Frédéric Béchet and Jackie Cheung -
ILLS Workshop 2024
Students presented their research in short talks and poster sessions at the lab’s annual meeting. Invited talks covered explainable AI, neuroscience and scheduling.
Workshop programme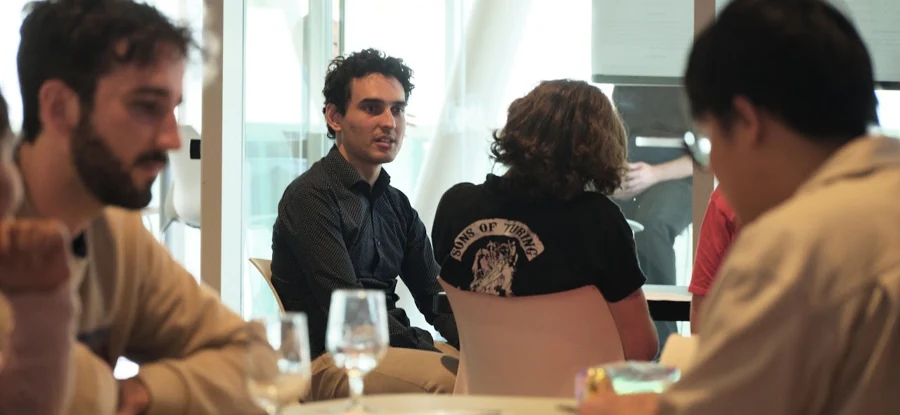
-
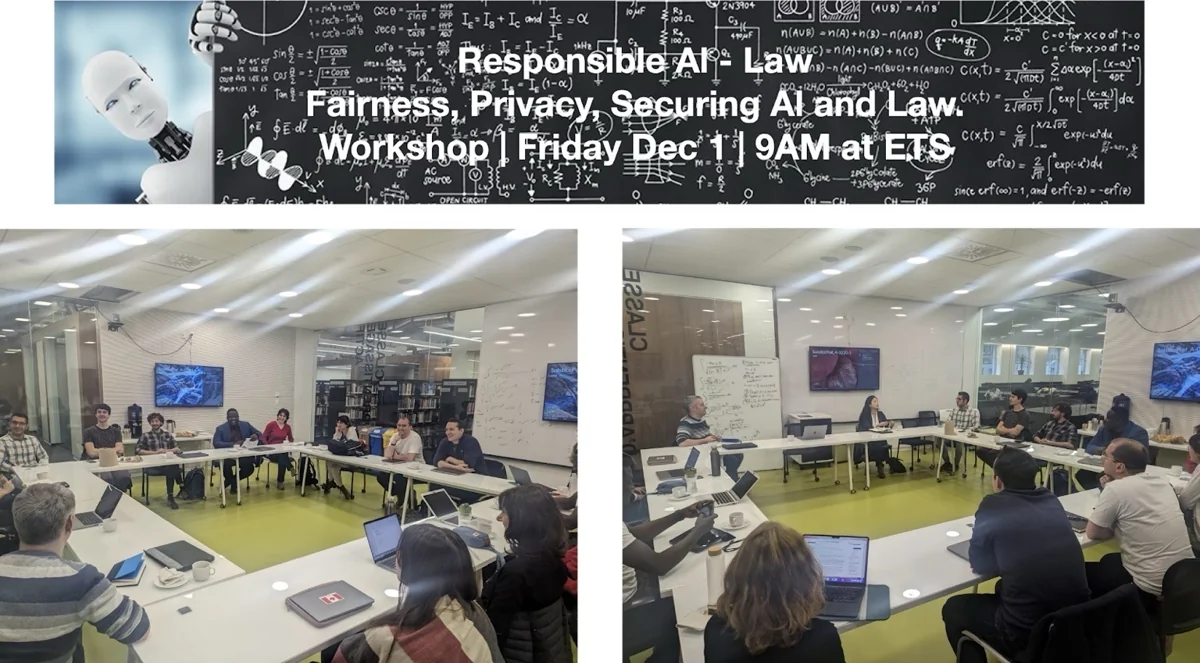
Fairness, Privacy, Securing AI and Law
Researchers in machine learning and law discussed how to assess algorithmic fairness, audit privacy risks and use the findings to inform AI governance.
-
Medical Imaging with Deep Learning
This ILLS workshop examined how to segment medical images, how reliably a model performs on unfamiliar data, and how to evaluate its predictions in a clinical setting.
Institutional visits
No institutional visits have been listed.
-
CNRS Computer Sciences leadership visits ILLS
Adeline Nazarenko, Director of CNRS Computer Sciences, and Jérôme Durand-Lose, Deputy Scientific Director for Europe and International Affairs, met ILLS researchers and students to discuss how the lab makes machine learning algorithms more reliable and safer to use. The delegation also met partners at IVADO, Mila, McGill and ÉTS.
Read the CNRS account of the visit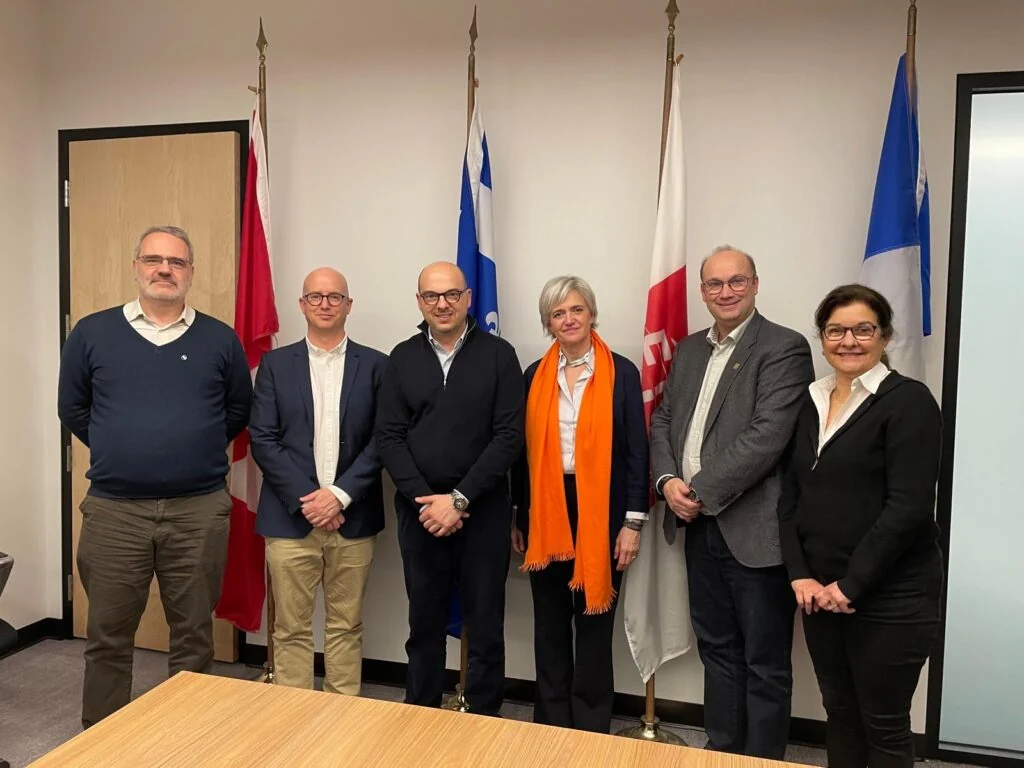
ÉTS Montréal · Photo © Andréa Dessen 
Mila · CNRS Ottawa -
ÉTS inaugurates Pavilion F, home to ILLS
Québec minister Martine Biron attended the opening of Pavilion F. ILLS researchers and students had moved into their dedicated space in the building earlier that year.
Read the ÉTS announcement (in French)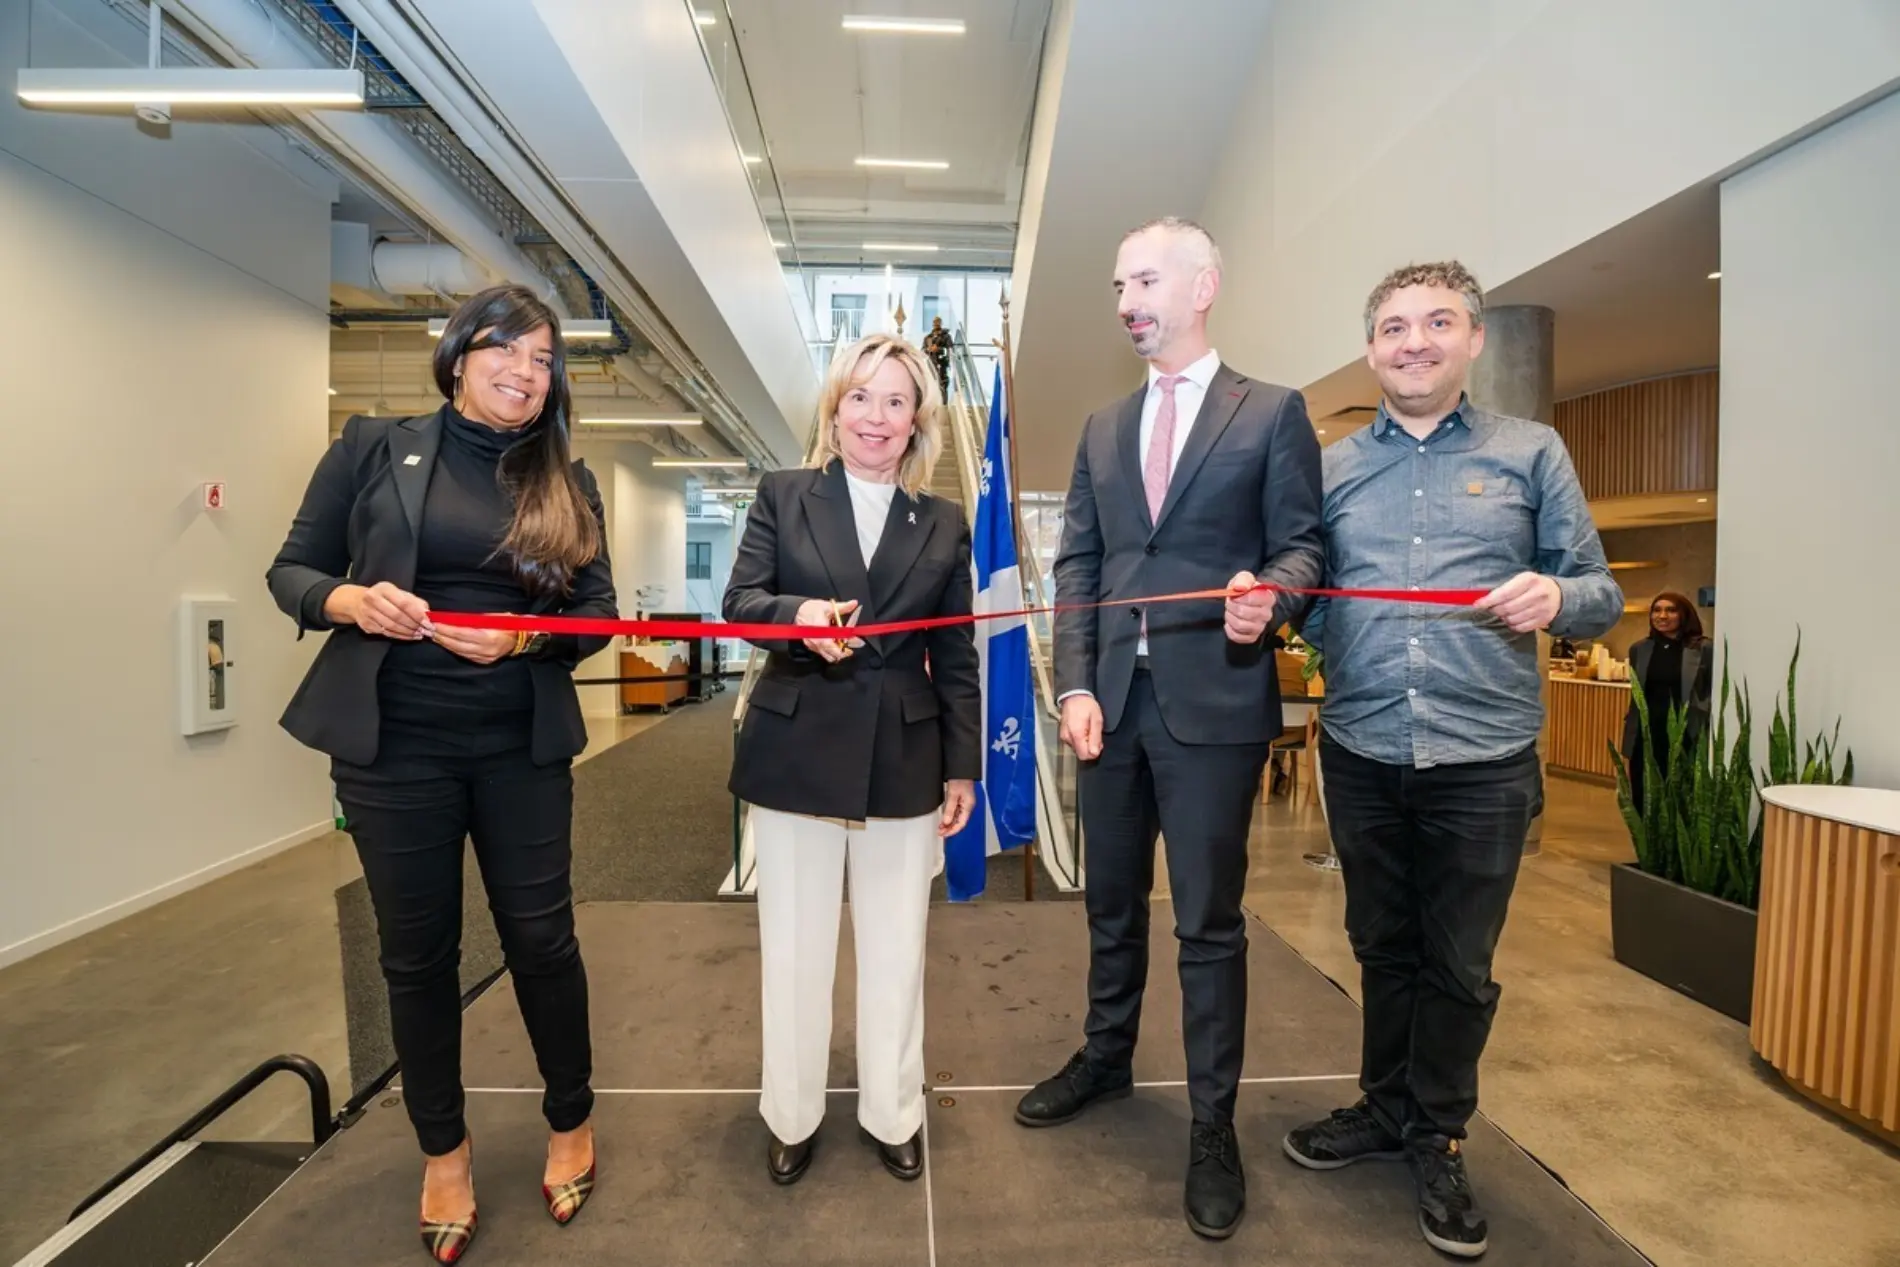
Photo © ÉTS Montréal 
-
CNRS delegation visits ILLS at ÉTS Montréal
Alain Schuhl and Christelle Roy met Pablo Piantanida, Mark Coates and members of the lab. Researchers and students presented their work through posters and lab tours and discussed future joint projects with the delegation.
Read the CNRS account of the visit (in French)
Photo © ÉTS 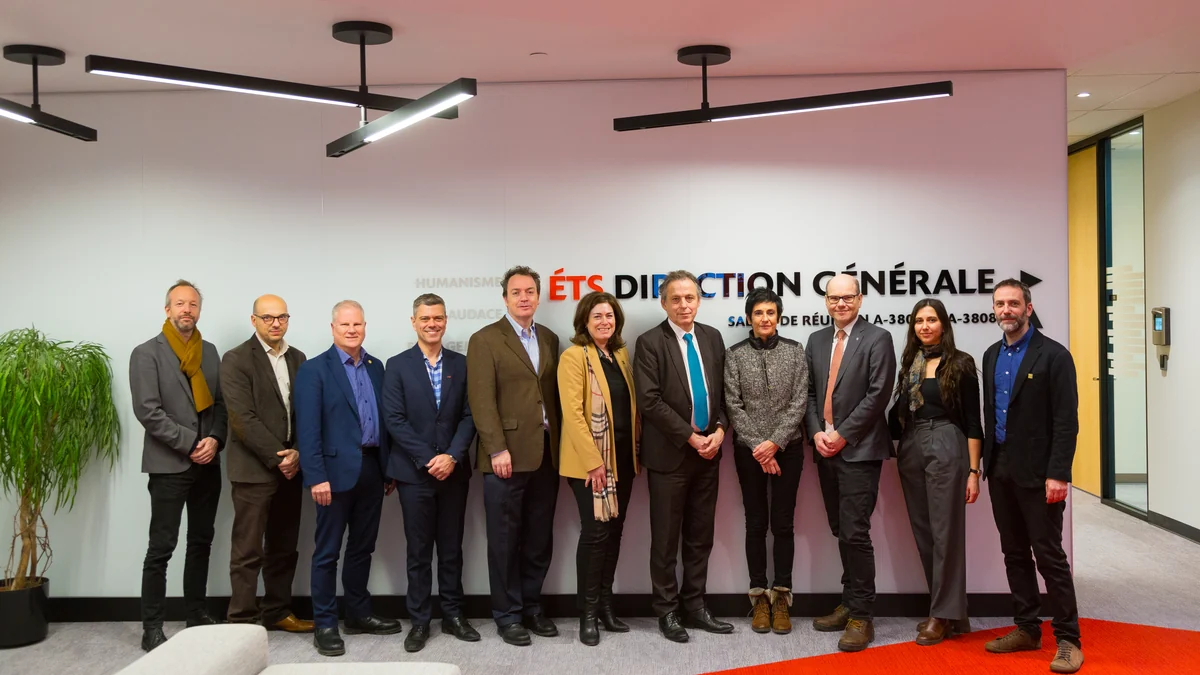
-
France’s Minister of Higher Education and Research Sylvie Retailleau meets the ILLS team
Sylvie Retailleau met ILLS researchers and students at ÉTS. Her visit to Canada coincided with the first meeting of the Canada–France Joint Committee on Science, Technology and Innovation.
View the French ministry’s visit programme (in French)